

Description
WordPress’ own “Uploaded to” column only tracks where a file was first attached — it says nothing about where a file is actually used. Files referenced from ACF fields, featured images, galleries, widgets, the customizer logo, WooCommerce product galleries or plain URLs in content all look “unattached”, and genuinely unused files look no different from files your site depends on.
Freshet Unused Media scans everywhere a reference can hide and tells you, per attachment, exactly where it is used — or that it provably isn’t.
A media library cleaner that shows its evidence: find unused images, delete or remove unused media, clean up the media library and free up disk space — without deleting a file something still shows.
What it detects
- ACF fields: image, gallery, file — including serialized values and repeater/flexible sub-fields, verified via ACF’s own field-key meta
- ACF blocks: field values stored inside the block markup, where no URL is ever written
- Featured images and WooCommerce product galleries
- Block editor content: image, gallery, Cover, Media & Text and Video blocks — read from the block’s own settings as well as from the markup it renders, so an image still counts when its web address has been rewritten to a CDN
- Classic content:
[gallery]and[playlist]shortcodes, page-builder shortcodes holding an ID (image="123"), and raw file URLs, including resized variants likephoto-300x200.jpg,-scaledfiles and percent-encoded filenames - Elementor page data
- Options and theme mods: site icon, custom logo, widgets, customizer settings — serialized or JSON
- Term meta and user meta (ACF fields on categories and profiles)
- Term descriptions — an image or an ID in a category, tag or product-category description
- Comments and comment meta (a file linked in a reply, review photos)
- Excerpts, and unsaved edits held in autosaves
How it works
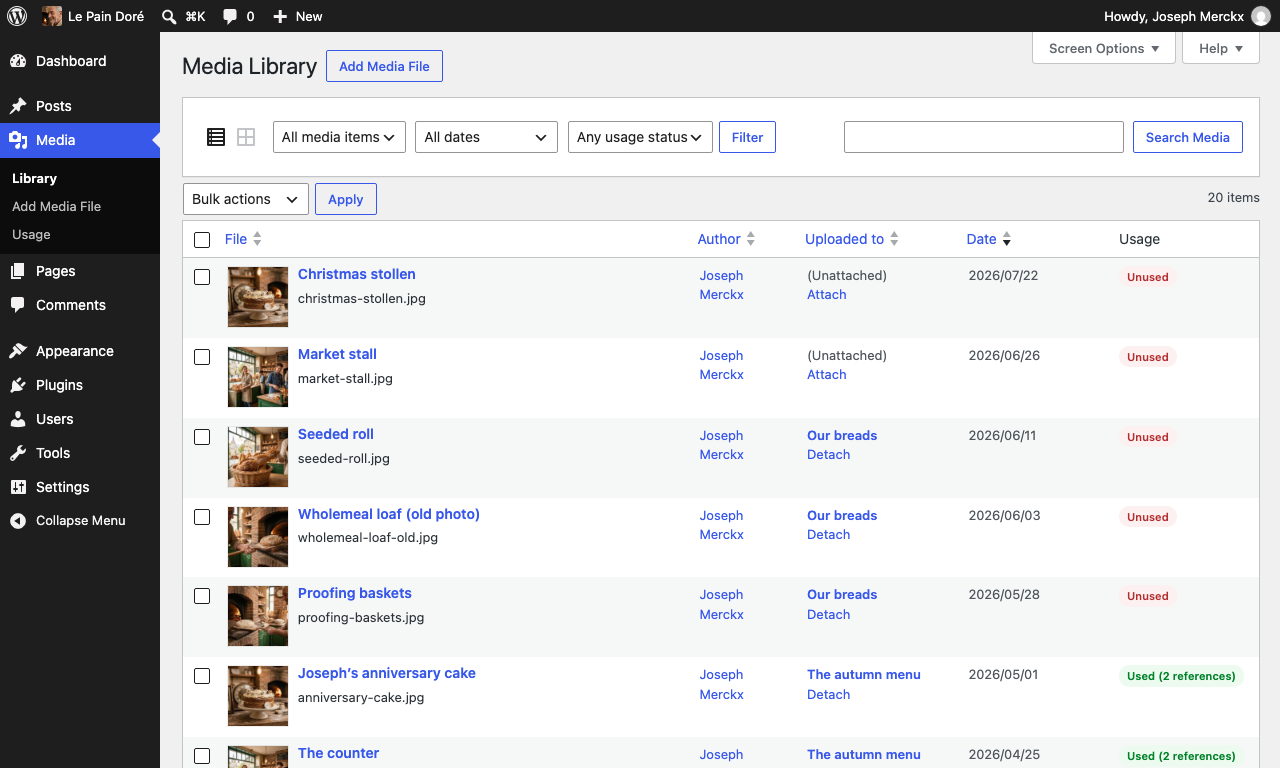
- A Usage column in the Media Library (list mode) with a per-file “Check usage” action
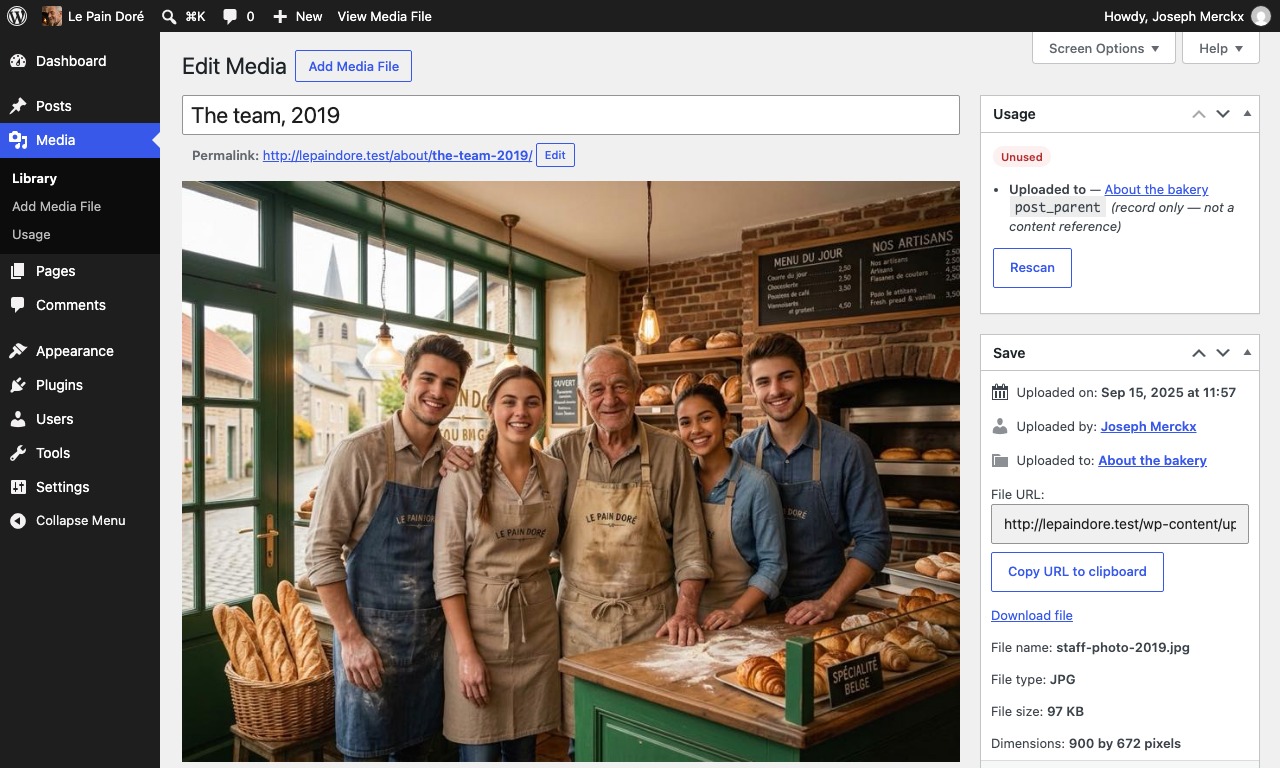
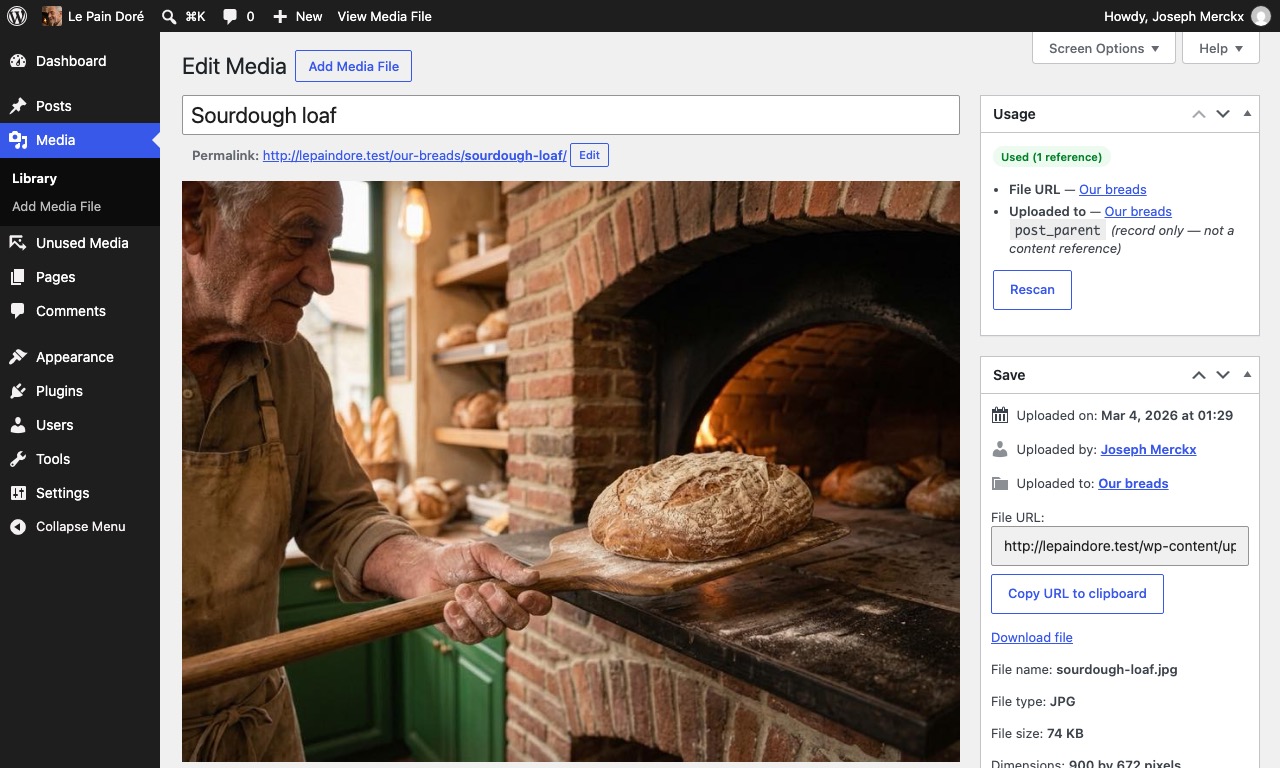
- A Usage meta box on the attachment screen showing the evidence: which post, which field, which option — with edit links
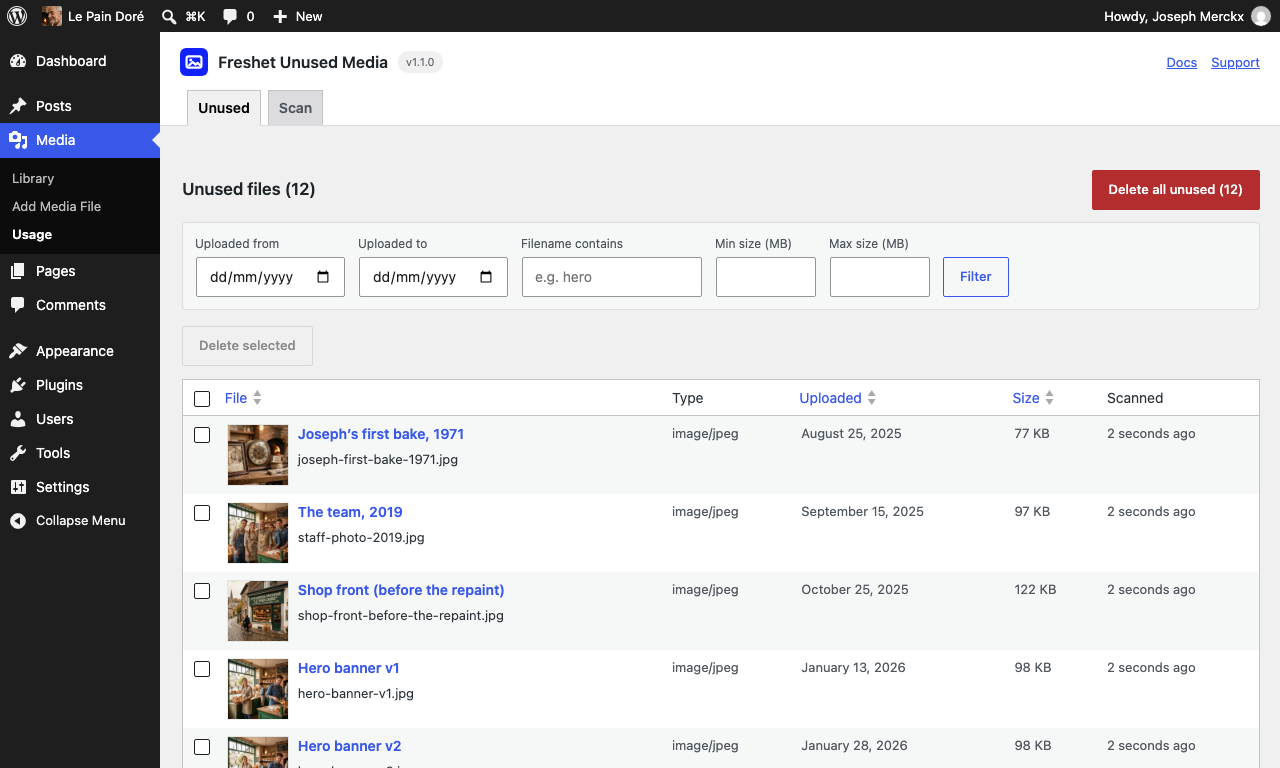
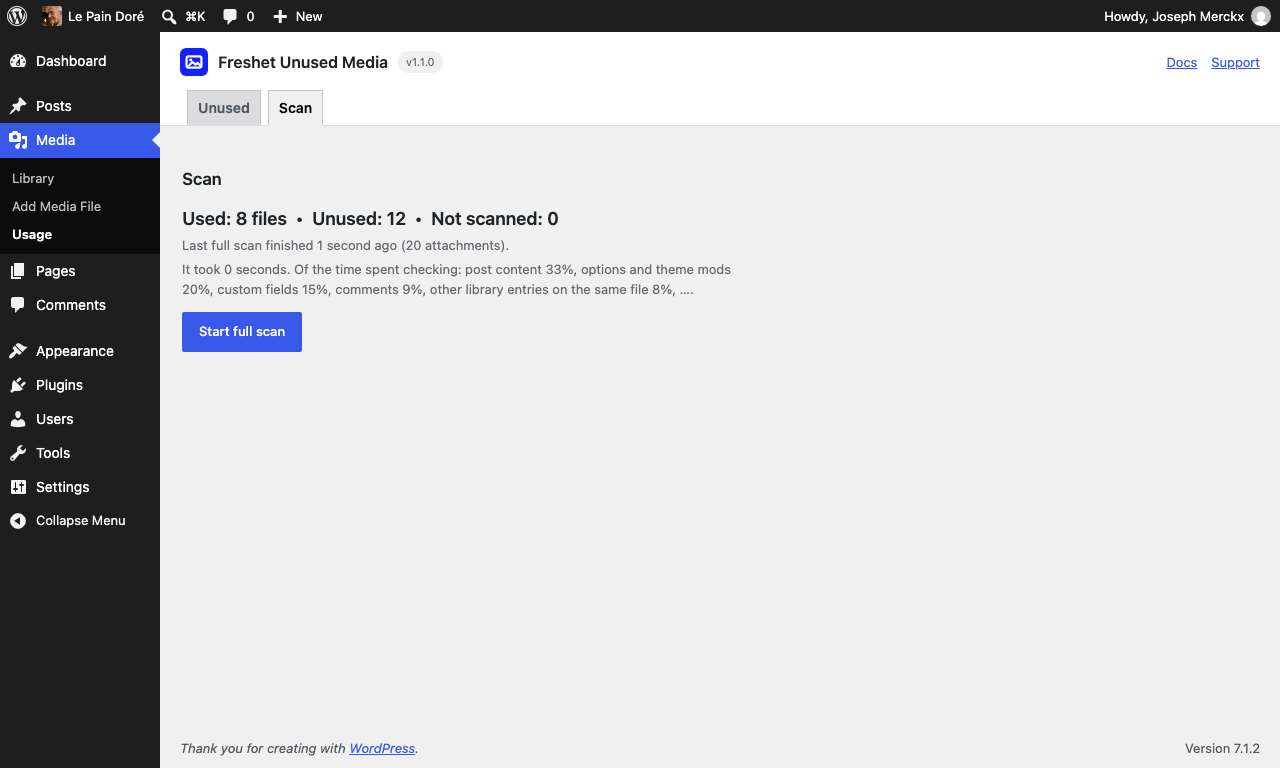
- A full-library scan on the plugin’s own Unused Media screen, directly below Media in the admin menu, that batches through your library in the browser and can be stopped and picked up later
- Safe deletion: delete selected or all unused files, each one re-checked before it goes
Why the answer can be trusted
Deleting media is destructive, so the scan is built to be wrong in one direction only — towards keeping the file.
- Ambiguity counts as used. A bare attachment ID in a meta key the plugin has never seen keeps the file. Matches are boundary-checked, so attachment 123 is never matched by
wp-image-1234. - Every file is re-checked in the instant before it is deleted. Anything that became used between the scan and your click is skipped rather than deleted, and the result tells you how many were skipped.
- A reference in the trash still counts. A trashed post or comment can be restored, so the files it uses are kept.
- Files uploaded in the last 24 hours count as in use — an editor may still be placing them — so a clean-up never removes work in progress.
- The evidence is shown, not summarised. Each reference is listed with the object it lives in, the field or option it was found in, and a link to go and look, so you can check the reasoning before you act on it. A scan stores the first twenty per file, confirmed ones first, and the badge above the list carries the number of confirmed places found — so a heavily-referenced file says how many there are rather than letting twenty stand in for the total.
- The reading is dated, and the screen says so. A scan reads the site’s content once and then answers file by file out of that reading, which on a large library takes hours. So the unused list describes the site as the scan read it rather than as it is this second, and both tabs print the moment it was read. A reference written while the scan was still walking the library is picked up by the next scan — and in the meantime the re-check above is what refuses to delete the file.
- The blind spot is written down. References kept inside a plugin’s own custom database tables cannot be found by any query-based scanner, and the FAQ below names that limit rather than leaving you to discover it.
How it stays safe
The list above is what a reader can check for themselves. Underneath it are the parts that cost a file if they are wrong.
- A database that stops answering is never read as “no references”. A failed query raises instead of returning an empty result, so the file keeps whatever status it had and the screen says the check could not be made. The quiet short answer is the one that deletes a file somebody needs.
- The unit of work is the file on disk, not the library entry. Several entries can point at one file — a duplicate import, a translation copy — and the file goes only once every entry standing on it is unused.
- Files that collide by name are held apart. An upload whose own name is already size-shaped, or a scaled upload whose original is some other entry’s file: both are cases WordPress unlinks by name without checking, including names that differ only in case. Those relations are read before anything is removed.
- The disk is read, not only the database. A generated size that has dropped out of an attachment’s stored metadata — after a theme change, an import, a thumbnail rebuild — is still one of that file’s names, and a page can still be showing it. Backup sizes, the sources behind WebP and AVIF copies and encoded filenames are read the same way.
- Size files whose original is gone are listed and never deleted. There is no library entry to corroborate them against, so they are reported for a person to judge rather than swept.
- The plugin’s own bookkeeping is outside what it reads. Its cursor, tallies and notes live in the same tables the scan searches, and a file was once reported used on the strength of the scan’s own numbers.
- A delete run is bounded by the clock, and the re-check is not what gives way. A deletion is one request with no second half, so it stops and hands the rest on while there is still time to tell you what it did — rather than being killed part-way having reported nothing. Nothing about the re-verification is skipped to fit a budget.
The “Uploaded to” relation itself is shown as informational evidence but never counts as usage — that unreliable signal is exactly what this plugin replaces.
Thoroughness is the point rather than speed: a first full scan of a large library can take hours rather than minutes. It runs in batches that stop before the PHP time limit and resume where they left off, so a scan always makes progress and can be stopped and picked up later. Two limits on that are worth saying out loud. Every scan is a full scan — there is no incremental mode, so the second scan of a library costs what the first one did. And a scan left idle for more than a day reads the site’s content again when you resume it, rather than finishing a listing onto a reading that old; that window is configurable, below.
Extensible
Site-specific detectors can be added via the freshet_unusedmedia_detectors filter, with a complete worked example — a detector reading a plugin’s own custom table — in README.md in the plugin’s source repository; freshet_unusedmedia_is_used gets the final say on any status; freshet_unusedmedia_batch_size and freshet_unusedmedia_batch_seconds tune scan batches; freshet_unusedmedia_upload_grace sets the recent-upload window in seconds (0 disables it); freshet_unusedmedia_index_max_age sets how long a scan’s reading of the site may sit idle before resuming it reads the site again instead (default 24 hours, 0 disables the check).
Part of the Freshet plugin suite. Full documentation: freshet.studio/docs. Questions and problems: freshet.studio/support.
Installation
- Upload the plugin and activate it.
- Go to Unused Media, directly below Media in the admin menu, and run a full scan.
- Review the unused list, then delete selected files or all unused ones.
Tip: add define( 'MEDIA_TRASH', true ); to wp-config.php so deletions go to trash instead of being permanent.
FAQ
Can it be wrong?
Detection is deliberately conservative: filename and structural matches are boundary-checked (attachment 123 never matches wp-image-1234), ambiguous ID matches count as used, and every file is re-verified right before deletion.
What it cannot see is anything outside the tables it reads — posts, postmeta, options, term descriptions, term meta, user meta, comments and comment meta. The blind spot most worth knowing about is inside your database, not outside it: references stored in a plugin’s own custom database tables — form entries, slider or page-builder records, any plugin that keeps attachment IDs or file URLs in a table of its own. No query-based scanner can find a reference in a table whose shape it has never seen. The same applies to references hard-coded in theme or plugin files, references held by an external service, references on other sites of a multisite network (network-wide options included), and the legacy Links manager.
Two deliberate choices are worth knowing too. Old post revisions are not counted as usage — a file removed from a post is meant to be found — but autosaves are, because they hold edits nobody has saved yet. And the re-check before deletion is not atomic: a reference written in the instant between the re-check and the deletion is not seen. That window is a fraction of a second; the recent-upload grace period covers the realistic case (a file placed in the editor before its post is saved), and MEDIA_TRASH covers the rest.
So: if a plugin on your site stores media in its own tables, check what it holds before deleting — and add define( 'MEDIA_TRASH', true ); (see Installation) so a deletion can be undone.
Does it delete unused images?
Yes, once the scan has shown that nothing on the site uses them. Images, documents, audio and video are all judged the same way: every place a reference can live is read, the evidence is listed per file, and a file with no reference anywhere is offered for deletion. Deleting removes the file and every resized copy WordPress made of it, or moves the entry to the media trash when MEDIA_TRASH is on. Nothing is deleted until you click a delete action, and each file is re-checked in the instant before it goes.
Is it safe to bulk delete unattached media?
No. Deleting on the strength of the Unattached filter deletes files that are in use. Media deletion in WordPress is permanent unless MEDIA_TRASH is enabled, so the references have to be searched for before anything is removed. Run the full scan first and bulk delete from the unused list instead: every file on it has been checked everywhere a reference can hide, and is checked once more before it goes.
How is this different from the “Unattached” filter?
Unattached only means the file was not uploaded from inside a post editor. WordPress records the post you were editing at upload time and nothing else, so a file used in a custom field, a page builder, a widget or a theme setting is shown as unattached while being displayed on the site every day. This plugin reads the places a file is actually referenced from: post content, custom fields (ACF included), featured images, galleries, options and theme mods, widgets, term and user meta, comments and raw URLs. “Uploaded to” is shown as information but never counts as usage.
How long does a full scan take?
Longer than a scanner that only looks at the “Uploaded to” column, because it looks everywhere else as well. On a large library the first full scan is measured in hours, not minutes. It runs in batches from the Unused Media screen, each batch stops before the PHP time limit and the next one resumes from the last completed file, so the scan always makes progress and can be stopped and picked up later. Every scan is a full scan: the stored results are what the lists are drawn from, but a new scan reads the whole library again rather than only what has changed since, so a second scan costs what the first one did. Nothing runs on a schedule — a scan happens when you start one.
Does a file referenced from the trash get deleted?
No. A trashed post or comment can be restored, so a reference from one keeps the file — it is reported as a possible reference rather than a confirmed one, and possible still counts as used.
What about files that are themselves in the media trash?
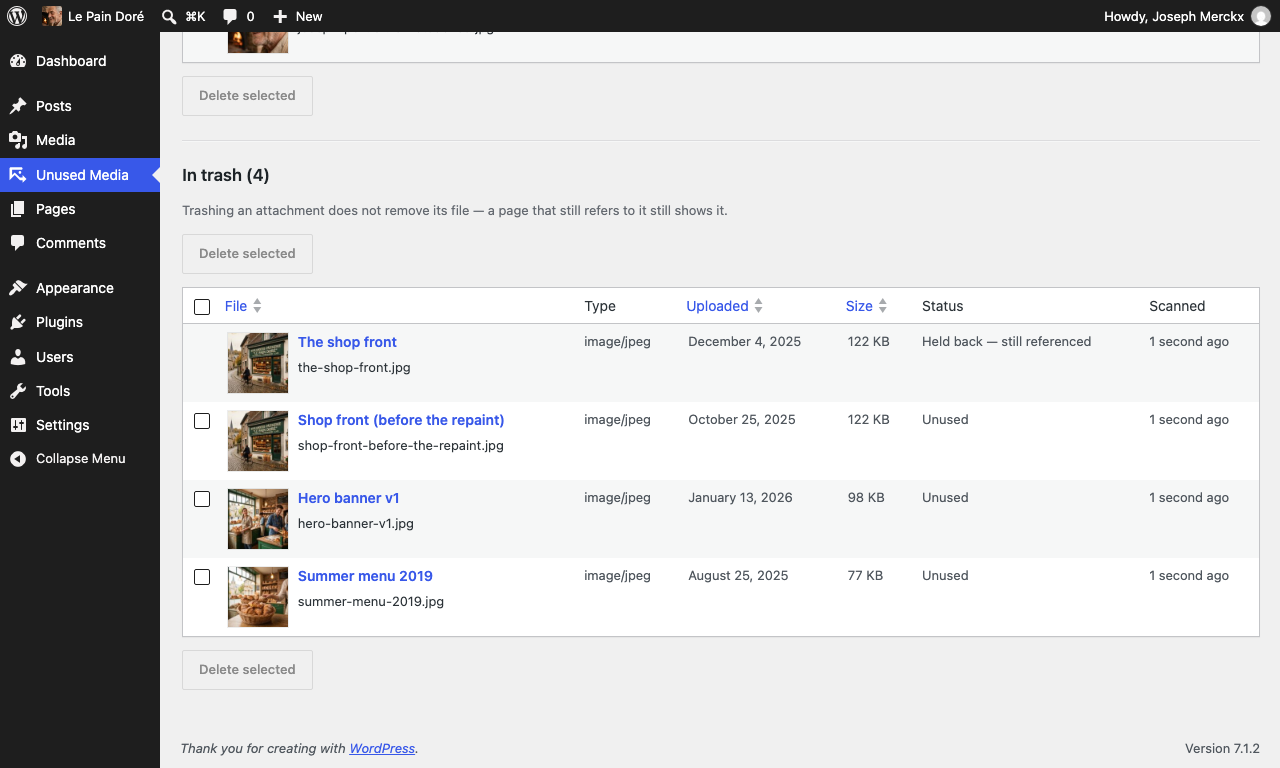
A file whose every library entry is in the trash is listed in its own “In trash” section under the unused list, and can be erased from there once the scan has found every entry unused — it never joins the unused list or its count, and a copy still in use is held back there too.
Does it work with multisite?
Untested, so treat a network install as unsupported for now. There is no multisite-specific code here: each site’s library would be scanned from that site’s own admin, which is how it is expected to behave, but nothing in this plugin proves that and the uninstall routine clears the current site only. Cross-site references — another site of the network embedding this site’s file URL, network-wide options included — are not detected in any case.
Does it delete anything by itself?
Never. Scanning only reads and caches results. Deletion happens exclusively when you click a delete action, after re-verification. Opening the page deletes nothing.
Where do I get help?
Write to the address on freshet.studio/support. Support is email, read by the person who wrote the plugin — say which plugin, which version, and what you saw, and a screenshot covers most of that in one go. Questions here in the WordPress.org support forum are read too.
Screenshots
Changelog
1.3.2
- The Usage panel no longer shows anyone where a file is used in places they can’t open. Everyone who can upload files sees the panel and its Check usage button, and it listed every reference the scan found — including the titles of other people’s private posts and drafts, the names of commenters awaiting moderation, and the internal names of settings. An administrator still sees all of it. Anyone else now sees a reference only where they could open the post, comment, category or profile it points to, plus one line saying how many more there are. Fresh checks by anyone who is not an administrator are limited to 30 every ten minutes, so the button can’t be used to load the server.
- A spreadsheet opening an exported CSV no longer runs a cell as a formula. A title or filename starting with
=,+,-or@went into the export as it was, and a spreadsheet could read it as a formula. Such cells now start with an apostrophe, which shows the text and runs nothing.
1.3.1
- “Content has changed since” now notices more than a post being saved. The note under the last scan only heard edits made in the post editor, so an import, a category description, a custom field, a widget or a setting changed after the scan left it saying the results were current. It now hears a change to anything the scan reads — posts and their fields, categories and tags, settings, user profiles and comments — including deletions. WordPress’s own housekeeping, the kind it does while a page is merely open, is left out so the note still means something. A change made by a direct database query, outside WordPress, is still not seen.
1.3.0
- A file is no longer offered for deletion on the strength of an old reading. A scan reads the site’s content once and then answers file by file out of that reading, and nothing checked how old it was. A scan resumed days later finished onto it, a Reset left the previous scan’s unused files ticked and ready, and Check usage and the check made in the instant before a delete answered out of it too — so a file put on a page since could read unused and go. Now a scan left idle for more than a day reads the site again when you resume it (
freshet_unusedmedia_index_max_agesets the window), a file whose reading was reset shows what it is waiting for instead of a checkbox, a file uploaded after the reading was taken is asked of the site, Check usage and the re-check before a delete always ask the site itself, and both tabs say when the reading was taken. - Sizes with no original are now figures you can act on, and a list you can keep. The Scan tab used to print their filenames — a hundred from any one folder at most and five hundred in all, with no sizes and no way to tell whether a page still showed one. It now says how many there are, how much space they take, and how many are used in post content against how many are referenced nowhere, with an Export CSV button that downloads every one of them: its path, its size, whether post content uses it and which posts do. The content check runs once, at the end of a scan, and reads post content the same way the rest of the scan does.
- A thumbnail made from the scaled copy of a large image is no longer reported as having no original. WordPress keeps a reduced
-scaledcopy beside a very large upload, and regenerating thumbnails can cut a second set of sizes from that copy. Those sizes were being listed as sizes with no original while their original sat in the same folder. On one long-lived library that was every file in the section. - A zero no longer reads as “none exist” on a site whose uploads live elsewhere. These files are found by reading the upload folders on this server, so a folder it cannot open contributes nothing. Where that happens the section now says None found on this server’s disk, and that folders it could not read were not counted.
- A file WordPress could not delete from disk is now said, not passed over. When the uploads folder is read-only, or an offload plugin refuses, WordPress removes the library entry and leaves the file where it was — and reports success either way. The delete notice now checks, and names those files as left on disk, so you know the space was not freed and where to look.
1.2.1
- A scan that will not start now tells you what the server said. The screen had one answer for every failure — Request failed — try again — whether the plugin knew exactly what had gone wrong or PHP had simply stopped. It had been writing an account of the refusal all along; the screen was fetching that account and throwing it away. You now read the plugin’s own sentence instead, so a scan refused by the database says The database did not answer one of the usage queries, which is a thing you can act on. Resetting a scan was worse again — its button had nothing to report with at all and just looked broken when it was refused; it reports now too.
- A failure with nothing to say names its status and where the cause is written down. When PHP stops outright — out of memory, out of time — there is no message to show, because nothing got as far as writing one. Rather than the generic line, the screen now says which status came back and that the reason is recorded in this site’s PHP error log, which is the only place it exists. That is the whole diagnosis on a server whose log you can read, and on one you cannot it is exactly what to ask the host for.
- The first scan no longer needs a database privilege plenty of hosts do not grant. Emptying the plugin’s own index used TRUNCATE, and MySQL carries that out by dropping the table and building it again — so it needs DROP, which a managed host has no reason to grant a site over its own database and which nothing else here wanted. Where it was missing the plugin installed, activated and drew its screens perfectly, and then the first Start scan was refused, every time, for good. It empties the table with a plain delete now: no special permission, and nothing else about a scan changes.
1.2.0
- A file is no longer reported as used hundreds of times by numbers that are not its ID. On a long-lived site a low ID — 7, 12, 40 — is a number the database is full of: a reading time in minutes, a form ID, a cache plugin’s hourly quota, the eighth entry of a stored list. All of those were being read as uses of the file with that ID, and one image on a fifteen-year-old library reported 212 of them, six of which it called confirmed. Not one was real. Four things changed. Keys whose number is documented to be something else — Yoast’s reading time and word count, W3 Total Cache’s own records, form IDs, WordPress’s own screen settings — are no longer read as IDs at all, while those same plugins’ image fields still are. A number inside stored data is now checked where it actually sits, so the position of an item in a list is no longer mistaken for the list naming file 7. A custom field is only treated as pointing at a file if the field is one that holds files — an image, a file, a gallery, or a link to the media library — which it asks the field’s own definition rather than assuming; a number field or a dropdown of form IDs is not. And the screens now separate the two kinds of evidence: the count beside Used is the number of places the file actually appears, and anything that merely might be the file is listed under it as a possible match, with its own count, worded so you can judge it. A file whose only evidence is possible is still kept — this plugin keeps anything it is unsure about — but it now says Held back — nothing confirmed, only possible matches rather than claiming a figure nobody could check. What can change is below the list of changes.
- The plugin’s own notes are no longer read as uses of a file, and two scans of a library nobody touched now agree. The scan keeps a few records of its own in the database — where it got to, how many references it has found, how many bytes it has reclaimed, which stray size files it noticed. Those records sat in the same place the scan searches, so the numbers in them were being read as file IDs and the filenames in them as filenames: a file could be reported as used on the strength of the scan’s own tally. It also meant the tally was part of what was being counted, so the same library could come out one reference different depending on where a scan was interrupted and resumed — two scans of content nobody had changed, disagreeing. Everything this plugin writes is now out of what it reads, so the answer is the library’s and the library’s only.
- A first scan that used to take hours now takes minutes, and a large library that could not finish one now can. The scan used to ask the database about every file in turn, so a library of a few thousand files meant a few thousand passes over the same content. It now reads the content once, writes down every reference it finds, and then answers per file from that. On the largest library this was measured against — 41,452 files — a scan that would have taken an estimated seventeen hours now finishes in about four minutes. Nothing about what counts as a reference has changed: files were checked against the old scan as well as the new one, and the two agree on every verdict and on every line of evidence.
- A scan no longer runs out of memory on a library with a very large number of distinct filenames. On a 27,000-file library it needed around 199 MB where PHP was allowed 128 MB, and the request died. It now finishes the same library inside 105 MB. A scan that still cannot get through stops and says what refused it, with its cursor where the last completed batch left it, so resuming carries on rather than starting again — and nothing is reported unused on the strength of a read that failed.
- A scan of a very large library now gets started at all. A scan works in short bursts, so the browser is never left waiting on one long request — and every burst was rebuilding the library’s whole list of resized copies from scratch before it read anything. On a 27,000-file library that rebuild alone took longer than a burst is allowed to last, so no burst ever reached the files and the screen ended on an error instead of a result. That list is now worked out once per folder rather than once per file: the same 263,632 names, in 0.67 seconds where it had been 16.33, and the old way and the new one were checked against each other on every single name before this shipped. The preparation for a library that size now finishes inside the first burst and the scan runs to the end. Nothing about what counts as a reference has changed, and the files on disk are still what the answer is read from.
- The screen has moved out of Media and now has its own entry in the admin menu, directly below Media, called Unused Media. It was Media → Usage. Same screen, same tabs, same address on the page — only the way you get to it is different, so a bookmark to the old one will need taking again.
- A scan that finished in under a second says so, instead of reporting “It took 0 seconds” and reading like a clock that had stopped.
- Other plugins’ messages no longer appear inside this plugin’s screens. WordPress moves every admin notice to the top of whichever screen is open, so a message about some other plugin’s media sync or translation settings ended up stacked inside this one’s panel, where there was nothing to do about it. Those messages still appear everywhere else in the admin – the Dashboard, the Plugins screen and every list – and this plugin’s own messages still show here. Nothing is hidden from you; it is only kept off the one screen where it cannot be acted on.
- An image placed with a Cover, Media & Text, Video or gallery block is now recognised by the block’s own settings. A block records the image it shows twice over: once in its settings, and once in the picture it draws. Only the picture was being read, which was enough for as long as the file’s own web address was in it — but a site that serves its media from a CDN rewrites that address away, and a template edited by hand can lose it too. Then the settings are the only record there is, and the image was reading as unused while it was on the page. Both are read now.
- A block in a widget area is read the same way. Widgets have been blocks since WordPress 5.8, so the image in one is in a block’s settings like any other — and if the block has since been flattened into plain HTML, the mark the editor left on the picture is now enough on its own.
- A captioned image is recognised by its caption. The caption wrapper names the file it was built around, which is what is left to go on when the picture inside it points somewhere else.
The three detection changes above each move a file from unused to used, and nothing that was reported used by any of them is reported unused now.
The ID change is the one that can go the other way, and it is worth a sentence. A file whose only evidence was one of the numbers described above — nothing but a reading time, a quota, a dropdown value, a figure out of the plugin’s own notes — has no evidence left, so it can appear on the unused list where it did not before. That is the correction, not a side effect: the file was never on a page. A file with any real reference, or any reference nobody can vouch for either way, is kept exactly as it was. Re-run a scan after updating, and read the unused list before deleting from it, which is what the evidence under each file is for.
1.1.0
- “Delete selected” is no longer live until you have ticked something. Pressing it with an empty selection used to ask you to confirm a deletion, then report “Deleted 0, skipped 0, failed 0” as a success — two steps that both read as if something had happened. The button now starts disabled and says what to do if you hover it, and lights up the moment a row in that list is ticked.
- The screens explain themselves a great deal less. The Usage box on the Edit Media screen has lost five of its six paragraphs: each of them restated the badge sitting directly above it (“Not scanned yet.” under Not scanned, “No references found anywhere.” under Unused). What is left is the one paragraph that names the other library entry holding a shared file, because it carries the only link to it. The Scan tab has lost everything below the scan button — the list of the places a scan looks, the line about ambiguity counting as used, the two reasons to run it again — and the In trash section is down from a lead and three points to the one sentence you could not have read off the screen. Nothing about what the plugin detects, judges or deletes has changed; the caveat about files uploaded in the last 24 hours now lives only on the Unused tab, which is the screen you are on when you go hunting for one.
- The delete confirmations count in the right unit, and now have a singular. They said “attachments” for a figure that has always counted files, and a list filtered down to one file asked “Delete all 1 unused files matching the current filter?”.
1.0.10
- Media → Usage puts the scan button where the scan is. The Scan tab now reads figures, when the last scan finished, then the button — the three paragraphs explaining what the scan looks at have moved below it, where they are still there to read and no longer sit between you and the thing you came to press.
- A rule now separates the unused files from the ones in the trash, so the In trash section reads as the different set it is rather than as more of the list above it.
1.0.9
- Less explaining, more screen. Media → Usage has lost the paragraphs that described what the lists already show: the intro above Used files, the note list above Unused files, and the two paragraphs around the Space figures. What is left is the heading, the figures and the files.
- The file lists now look like the Media Library. Thumbnail on the left with the title beside it and the filename under the title — the same arrangement WordPress uses on Media → Library, instead of the filename dropping to a line of its own below the thumbnail.
- “Delete all unused” is a filled red button rather than red text, so it can be found on the heading row without reading for it.
1.0.8
- Scans now show how far along they are and how long is left. While a scan runs, the bar under Media → Usage says how many attachments it has done out of how many, how long it has been scanning, roughly how much of it is left, and which check the time is going into — “checking post content”, “checking custom fields”. A scan of a big library no longer looks like a screen that has stopped responding.
- The estimate counts only the time the scan actually spent. Stopping a scan and resuming it tomorrow does not make it claim a week’s work: the hours nobody was scanning are not in the figure.
- A finished scan says what it cost — how long it took, and how the time was split across the checks (“post content 41%, custom fields 33%, …”). It stays on the screen after the scan, which is where the question is actually asked: before starting the next one.
- The plugin’s header strip on Media → Usage now sits flush at the top of the screen and runs its full width, instead of starting a short way in with a gap above it.
1.0.7
- The listing, not the scanner. Nothing about how the plugin scans or deletes has changed since 1.0.6. This release carries the wordpress.org listing: a readme that says what the plugin does in the words people search for — find unused media and unused images, clean up the media library — with three new FAQ entries on deleting unused images, on why bulk-deleting “unattached” files is unsafe, and on how this differs from the Unattached filter; five real screenshots of the Scan tab, the Unused tab, the Usage column and the Usage box; and a Playground blueprint so the plugin can be tried in the browser from the listing.
1.0.6
- Files whose every library entry is in the trash are listed in their own “In trash” section under the unused list, with their own count and their own checkboxes. Trashing an entry removes no file, so a binned file a page still shows is held back there rather than offered, and one the scan has not reached is shown as not scanned; erasing one from this section is the permanent half of the media trash. The unused list, its count and its delete pool are the library’s and do not move.
- The plugin no longer registers its own translation loader — WordPress loads wordpress.org language packs itself.
1.0.5
- A folder whose name is written in a different case is now read once. The claims index looked a directory up case-sensitively while the database folded case, so on a server that treats
2026/09and2026/09as one folder the same files could be read under two scopes — and a file’s own claim could be missed. One scope per folder now, however it is spelled. - A file’s question is asked once per batch rather than once per row standing on it. Where several library entries share one file on disk, the scan repeated the same reads for each of them. The answer is shared across the batch now: the same verdict, measurably less work on libraries where copies are common.
- Housekeeping. A translator note on the Unused label’s placeholder, and the wordpress.org listing artwork.
1.0.4
- A reference written in a different case now counts. Rows naming a file or an ID are fetched case-insensitively by the database and were then thrown away by a case-sensitive check — so a link written
HERO.JPGagainst a file storedhero.jpg, or markup carryingDATA-ID="123", kept nothing in use and the file was offered for deletion. Both halves agree now, accented filenames included. - Two spellings of one filename are no longer counted as one library entry. The database folds case where the plugin did not, so
Hero-Banner.jpgandHERO-BANNER.jpgwere one group in the count and two in the list. Each is its own file now, and where the server’s filesystem would treat them as the same file a deletion refuses it rather than removing a file the other entry still stands on. - A count that could not be read now says so instead of reading zero. Where a query failed, the Scan tab reported “Unused: 0” for a library it had not managed to look at. The figures now stand at a dash under an error notice, a listing that could not be read is not drawn at all — so there is no empty table and no Delete all button naming a set nobody counted — and
wp freshet-unusedmedia scanends on an error instead of a success line, leaving--resumeto carry on from the last completed batch. - Delete all now reports as much as the checkbox form. Its progress bar sat at 0% for the whole run and rendered below the table, out of sight of the button that started it, so a long deletion looked like a screen that had stopped responding. The bar now sits under the button and shows real progress, and the completion message names what was deleted, skipped and failed, and how many files the run did not reach.
- A file another library entry stands on is now held back at the scan, not only at the delete. Where one entry’s resized copy or pre-scale original was itself uploaded separately, the file read as unused, was listed, and was then quietly skipped when you tried to delete it. It now comes back used, with the reason on its own row and the entry that would lose a file named in the evidence panel.
- An attachment’s own description and caption are searched. WordPress keeps both on the attachment itself, and the scan excluded those rows outright — so a file referenced only from another upload’s description or caption was reported unused.
- A file named only by an unsaved draft’s custom fields now counts as in use, the way one named in that draft’s text already did. Old revisions still do not count.
- An image pasted into a comment out of the block editor is recognised by the ID the editor writes (
class="wp-image-123"), where only a plain file URL or an attachment-page link was read before. - The Scan tab leads with its figures. The three numbers the tab exists for sat at body size between two paragraphs of helper text; they now open the section, with the scan’s timestamp and everything that qualifies them underneath. The explanatory copy on both tabs is shorter and reads as points rather than paragraphs, with nothing it said dropped.
- Deleting from a library where several entries share one file is substantially faster: each file’s checks now run once for the whole group instead of once per entry. On a large library a five-file request fell from about 102 seconds to 70.
- A scan whose attachments hop between upload folders no longer re-reads a folder for every attachment, so scanning a library whose uploads are not in folder order is faster.
Earlier
- 1.0.0 to 1.0.3 — the first release, then the detection and deletion-safety work that followed it. Their full notes are in the readme of each of those versions.